fullstackAI-assisted since Oct 20262024 – now
bignews.day
https://bignews.day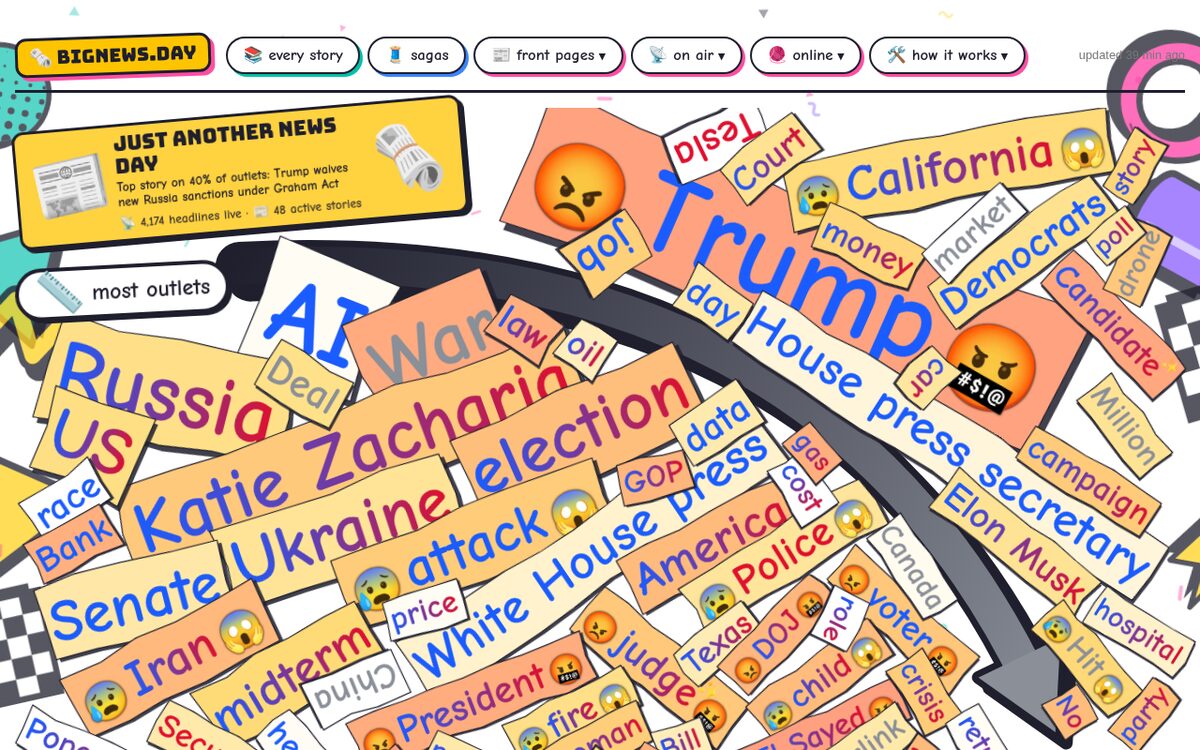
bignews.day watches how the news gets told. It reads the front pages of 145 outlets around the clock and follows each story outward: through wire copy, TV chyrons, radio newscasts and podcasts (transcribed on my own machine), the claims people make about it on social media, and what fact-checkers examine. Headlines are clustered into stories, and stories into multi-part sagas that run for days or weeks.
The newest layer is a motif index: a catalog of the recurring shapes political stories take (the owned politician, the senile leader, the carpetbagger...), built bottom-up from real claims and read against folklore scholarship like Thompson's motif index. Local models propose where a claim belongs, and a confidence model trained on my own decisions scores their proposals.
Every model runs locally on a single 10 GB GPU, and each one is chosen by testing the candidates against my own judgments rather than public benchmarks. A methods log dates every change to how things are measured, so a chart that crosses one can be read with it in mind.
History
This is the third version. The first, Maudlin (2021), was a Flask app built on scrapy. The second, Maudlin News (2024), I built by hand: my own multithreaded spider framework over 114 scrapers, sentiment analysis with VADER and AFINN, and a story clustering algorithm of my own design. After trying HDBSCAN and k-means, I settled on TF-IDF cosine similarity, thresholded into a graph whose connected components are stories, and moved the graph search into a C extension for a 10x speedup. It generated a static site that I deployed to Netlify.
In October 2026 I restarted it as bignews.day, building with Claude. That's how it grew this far, this fast.